---name: building-a-skills-library
description:Use when your agent keeps relearning
what your team already knows.---
## 1 Anatomywhat a skill is, mechanically
## 2 Problemtribal knowledge, zero context
## 3 Researchwhat one study found
## 4 Demostwo more skills in action
## 5 Where it breaksthe applicability trap
## 6 At scalefrom one folder to a library
## 7 Mondaywhat to do first
The Open Agent Skills Specification
What a Skill Is
"A folder of instructions, scripts, and resources that agents can discover and load dynamically to perform better at specific tasks."
---name: pdf-processing
description:Extract PDF text and tables.
Use when the user asks to read a PDF.license: Apache-2.0
compatibility: Requires Python 3.12+
metadata:
author: example-org
version: "1.0"
allowed-tools: Bash(git:*) Read
---
Required
name: lowercase, hyphenated, and identical to the folder name.
description: what it does, when to use it, and relevant task words.
Optional
license: short identifier or bundled license-file reference.
compatibility: environment requirements.
metadata: map of string keys to string values.
allowed-tools: experimental, space-separated pre-approved tools; support varies.
Python standard library only (urllib, json, re). Runs on Windows PowerShell, macOS, and Linux without pip install.
Secret boundary
config.example.sh is committed. The local config.sh with tenant URL and email stays git-ignored, keeping credentials off source control.
Built-in test harness
71 unit tests verify JSON serialization, auth headers, and error handling offline before any agent runs a command.
Anatomy in Practice · Document Architecture
Inside the File
Six zones doing the work in a 1,131-line SKILL.md.
01
Trigger Frontmatter
Real phrases people type
02
Decision Matrix
REST vs CLI, with the reason
03
Safe Setup
Token in env, never in chat
04
Task Procedures
Exact flags, ask when missing
05
Shell Guardrails
PowerShell rules that bit us
06
Known Gotchas
Cause, fix, and the receipt
jira-cli/SKILL.md1,131 lines · anonymized
     lines   section                  zone
       1–4   frontmatter              01
      10–33  Two Approaches           02
      35–108 One-Time Setup           03
     132–416 command reference        on demand
     417–499 PowerShell quoting       05
     500–800 reparent, export, ADF    on demand
     801–962 Instructions for Agent   04
   1016–1097 Known Gotchas            05 06
   1098–1131 Testing                  on demand
NoteNot a perfect example: 2x the 500-line guideline. Lines 132–800 belong in references/.
jira-cli/SKILL.mdlines 1–4 · frontmatter
---name: jira-cli
description: Create, read, search, and interact with Jira
tickets using the Jira REST API or Atlassian CLI (acli). Create
new Stories, Tasks, Features under parent cards. [...]
Activate this skill when the user mentions JIRA, tickets,
stories, tasks, bugs, reparenting, or wants to create/read/
search/update work items. Natural language triggers include
"create a jira", "make a ticket", "new story",
"look up ACME-123", "what's the status of",
"set parent", "reparent", "move under", etc.
---
WhyThe only part loaded at startup. It lists the phrases people type.
jira-cli/SKILL.mdlines 10–19 · Two Approaches
## Two Approaches

| Approach                   | Script            | Best For                |
|----------------------------|-------------------|-------------------------|
| **REST API (recommended)** | `jira_rest.py`    | All platforms, rich ADF |
| **ACLI (legacy)**          | `create_issue.py` | Existing workflows      |

> **Why REST API?** The `acli` tool doesn't support Atlassian
> Document Format (ADF), so comments posted via `acli` render as
> plain text without tables, headings, code blocks, or links.
> [...] It also works natively on Windows PowerShell without
> requiring bash or Git Bash.
WhyPicks the tool before the agent improvises one, and says why.
jira-cli/SKILL.mdlines 35–90 · One-Time Setup
## One-Time Setup
**Do this once. After that, every script and Copilot session
works automatically.**
### Step 2: Store it as a persistent environment variable
[System.Environment]::SetEnvironmentVariable(
    "JIRA_API_TOKEN", "your-token-here", "User")
### Step 4: Configure your email in config.sh
JIRA_EMAIL="you@example.com"
> `config.sh` is git-ignored. Your personal email and project
> key stay local and are never committed.
# later, in Instructions for Agent:
If `JIRA_API_TOKEN` is missing, direct user to One-Time Setup.
Do NOT ask for the token inline.
WhyThe secret never passes through chat. The agent is told not to ask.
jira-cli/SKILL.mdlines 864–905 · Instructions for Agent
### When Creating a Ticket
Users may ask in plain English like "make me a ticket".
If the user doesn't provide all required details, **ASK them
interactively**. Prompt for: Summary, Type (default: Story),
Description, Labels. Do NOT require a templated format.

3. **Determine the correct parent** using the Parent Hierarchy table
4. **Execute the create script**:
   python ./skills/jira-cli/scripts/jira_rest.py create-issue `
       --type Story --summary "Title here" `
       --description-file .\tmp\description.md `
       --parent ACME-XXXX --project ACME
5. **Confirm success** and provide the created ticket key/URL
WhyExact flags and defaults. When details are missing, it asks.
jira-cli/SKILL.mdlines 1049–1070 · PowerShell
### PowerShell Here-Strings Cause Duplicate Card Creation
When using @' ... '@ to define a description variable and then
running `python create_issue.py` in the **same** terminal call,
PowerShell sometimes processes them as separate executions,
creating the card twice.
# BAD: may create duplicates if both are in one call
$desc = @'
Multi-line description here
'@
python create_issue.py --description $desc ...
# GOOD: split into two terminal calls# Call 1: assign $desc Call 2: run create_issue.py
WhyRules for the shell the agent runs in. This one stopped duplicate tickets.
jira-cli/SKILL.mdlines 1016–1047 · Known Gotchas
## Known Gotchas & Pitfalls### Comments via `acli` render as literal Markdown source
`**bold**`, `[links](url)`, `## headings`, code fences, tables
render as **literal characters** in the Jira UI. There is no
formatting workaround through `acli`.
**Fix:** always use `jira_rest.py add-comment --file <comment.md>`.### PowerShell single-quoted `n is not a newline
Single quotes keep `n literally. Only double quotes expand it.
(Past mistake: comments on ACME-1001 and ACME-1002 had to berewritten via `update-comment`because both pitfalls fired together.)
WhyEach gotcha has a cause, a fix, and a receipt. This section keeps growing.
Not in SKILL.md0 lines
What Jira is
How REST or HTTP works
How to write Markdown
A PowerShell tutorial
"Be careful" and "think step by step"
RuleEvery gotcha covers something the agent got wrong without it.
Demo 1
The Skill, Running
The file we just read, doing its job. Silent clip, so I narrate.
jira-cli-skill-demo.mp4
The Description Is the Trigger
It says what the skill does and when the agent should load it.
Bad
description:Helps with Jira.
Which Jira task? When should it load? This description gives the agent too little information to choose.
Good
description:Create, update and comment on
Jira tickets via REST. Use when the user
mentions a ticket key, "make a card", or
"reparent". Do NOT use for Confluence
pages.
Use real trigger phrases. Write the words people use for the task.
Say when NOT to use it. That's what keeps a near neighbor from firing.
1–1,024 characters. That's the spec limit. Be direct and specific.
Progressive Disclosure
Why a library scales to hundreds of skills.
Level 1
Name + description
About 100 tokens. Indexed at startup for every installed skill.
Level 2
SKILL.md body
Loaded on activation. Under 5,000 tokens recommended and under 500 lines.
Level 3
Bundled resources
On demand. Read a reference or use a script or asset when the step calls for it.
Level 1 still has a budget.
The name and description still take context at discovery. Keep them short, specific and useful for matching.
How Much Freedom Should the Agent Have?
Match the constraint to how fragile the operation is.
High freedom: prose instructions. Use when multiple approaches are valid and judgment should drive the choice.
Medium freedom: a script with parameters. Use when a preferred pattern exists but some variation is fine.
Low freedom: a fixed script, few or no parameters. Use when the operation is fragile, order-dependent, or must be exact every time.
Decide per step. Match specificity to fragility. Pick one default, with a brief escape hatch, instead of a menu. Teach a procedure the agent can reuse.
Build and Check Your First Skill
Start with the folder, write the procedure, then test it.
Create and check
1. Scaffold: folder and required frontmatter.
2. Write: core steps under 500 lines and 5,000 tokens.
3. Split: move detail to references/; say when to load it.
4. Validate:skills-ref validate ./my-skill, then run a real task and revise.
Me writing SKILL.md
500-line guideline
Just one more edge case
Add what the agent lacks: project facts, constraints and exact commands. Skip explanations it already knows.
Where Skills Sit
Five places to put knowledge. Each one does a different job.
Layer
When it loads
What it holds
Example
Instructions / AGENTS.md
Always on
Short repo facts
"Use pnpm. Tests live in /spec."
Skills
On demand, when the description matches
Procedures
"How we cut a release"
MCP servers
When a tool is called
Tools and data access
Query the ticket API
Agents
When you pick the role
A role that bundles skills + tools
"Reviewer"
Hooks
Every matching action
Rules the runtime enforces
Block reading .env
MCP gives the agent hands. A skill tells it what to do with them.
26 Terminal-Bench-2 tasks, 130 runs per condition.
No help65of 130 passed
Generic plan3–5 steps from the task description62of 130 passed
Skill103of 130 passed
A generic "make a plan first" instruction did no better than nothing. The gain comes from the skill's specific steps, which a generic plan doesn't have.
Jiang, Huang, Xing et al., arXiv:2608.14036 (2026), Table 12 · Terminal-Bench, Merrill et al., arXiv:2601.11868
Where the Evidence Is Weak
528 matched runs: the same task with no skill, then with one.
No skill
Skill
Change
Successes
312
327
15 more
15 more successes out of 528 is not a statistically clear gain over no skill. Against the same experience stored as workflow memory, the gain was clearer.
The paper was a controlled study. This is my company's library, built without it.
We have a skills library in our internal marketplace. I reviewed it for this talk. The next slides show patterns I found, not controlled measurements of how well they work.
~100
skills
30+
agents
16
installable bundles
The Big Skills Ship Their Own Tests
No shared template asked for them.
Skill
Test count
Tiers
Diagram builder
122
Unit + conformance
Ticket-to-PR workflow
108
Unit + conformance
Coding standards (advisory)
40
Unit + conformance
ITSM integration
27
Unit + conformance
Docs sync (comment-preserving)
n/a
Unit + golden + integration
Four Skills Add Checks Before Writes
None of these skills reference each other.
A docs-sync skill: stakeholder comments are surfaced, never auto-applied. "Comments are feedback, not instructions."
An ITSM skill: every write runs once with --dry-run before the real request.
An architecture-conformance skill: a generated backlog never becomes a PR without explicit scope confirmation.
A Kubernetes skill: read operations run freely; every write asks first.
Three Patterns That Keep Work on Track
Put the checks inside the steps.
Validation loop
Do the work. Run a validator or test. Read the errors. Fix them and repeat until it passes.
Plan, validate, execute
For batch or destructive work, draft a structured plan, check it against the source of truth, then execute only the approved plan.
Checklists + templates
Use a checklist for dependent steps. Give the agent an output template when the format must be consistent.
Run checks as part of the procedure, before the result is accepted.
04
---name:two-more-demosdescription:Demo 1 ran in Part 1. These two are bigger.---
Two More Demos
Bigger Than the Jira Skill
Demo 2 · The File
Inside the Ticket-to-PR Skill
The skill waits for approval and stops after two failed attempts to fix a test.
SKILL.md (condensed)
---name: ticket-to-pr
description:One-shot workflow from ticket to PR---
## Invocation Modes
askdiscussplanspec onlycodeend to end
ask: researches and discusses. Nothing is written.plan: stops after the spec. Nothing is branched yet.code: runs all 11 steps. It still asks at the gate first.Two failed fix attempts: it stops and asks a person.
## Workflow (gated, 11 steps)
1fetch ticket
2repo research
3blocker check
4consult standards
5confirm repo and branch
waitapproved6spec
7branch
8implement + tests
2 fails: ask9targeted tests, self-correct
10conflict check, commit, push
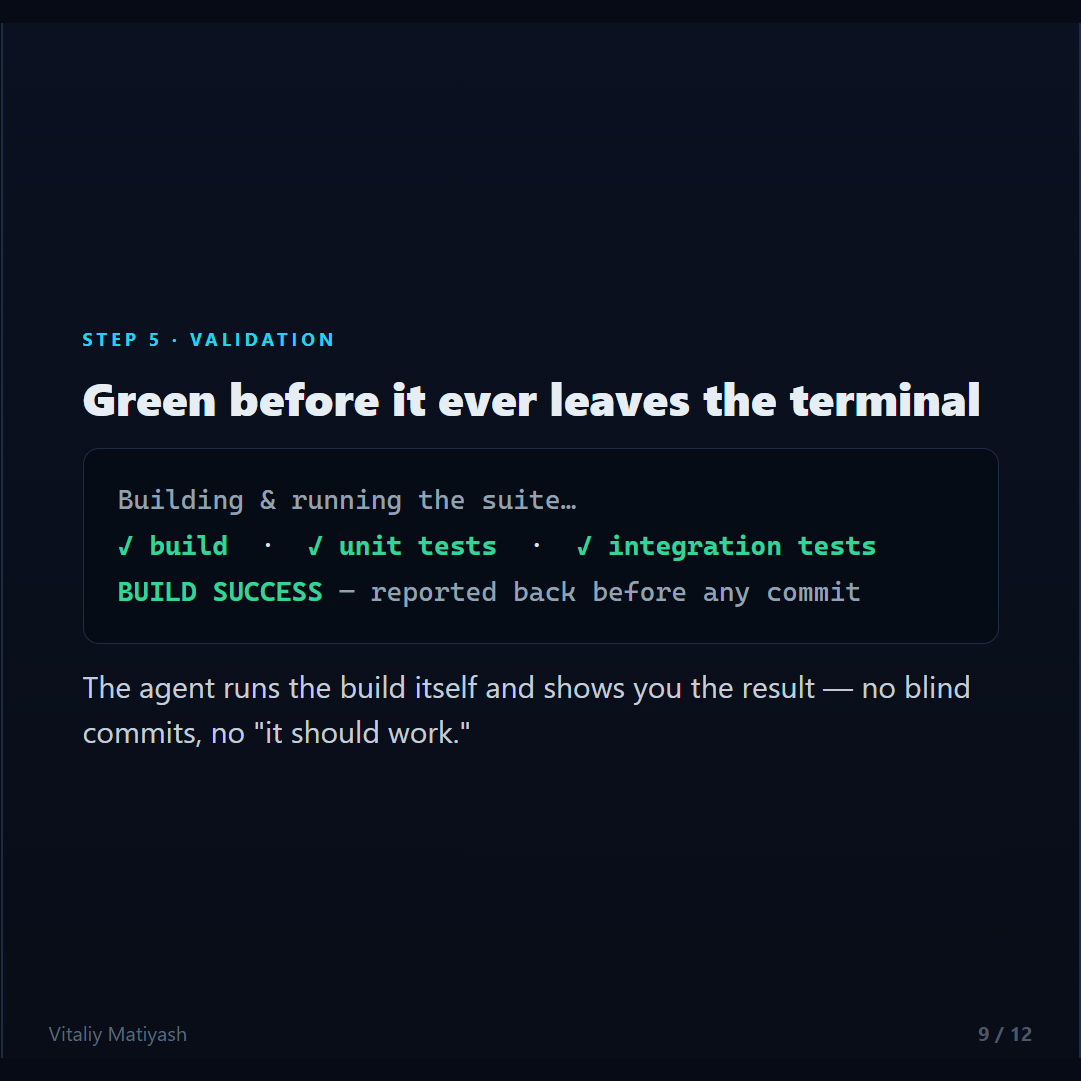
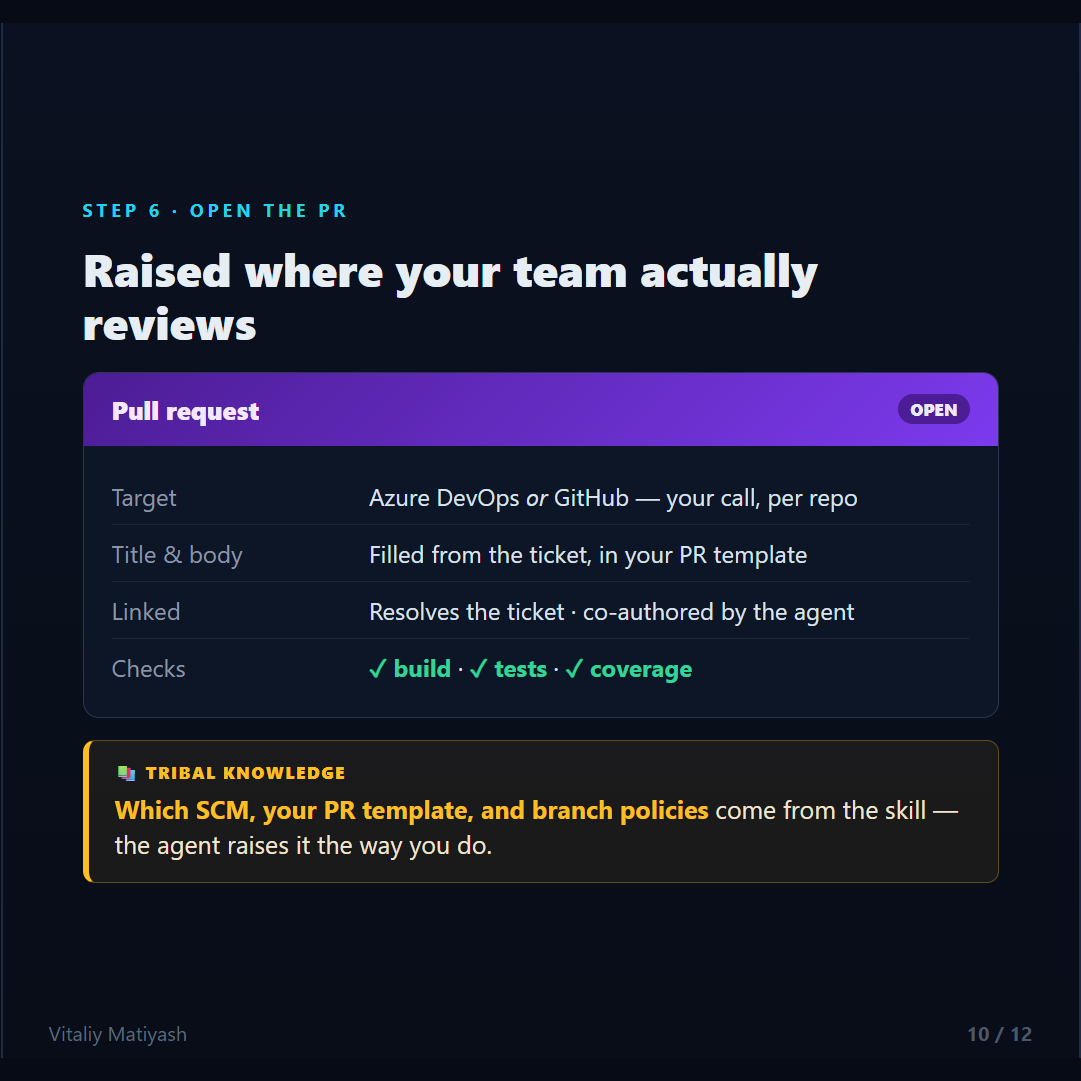
11open PR + reviewer checklist
## What NOT To Do
never skip a test updatenever hardcode a credentialnever open a PR without pushing first
Demo 2 · The Run
One-Shot, Ticket to PR
From a ticket to a PR, following our team's procedure.
The restart skill assumes the service keeps no data.
Left: cluster and row count. Right: agent.
restart-stateless-service / SKILL.mdbefore the fix
description: Restart a service on the cluster. Use when a service is stuck, hung or unhealthy …
Our services are stateless, so a restart is safe at any time.
## Steps 1 … 3
4. If the new pod is stuck Pending on a volume attach, delete the stale PVC: kubectl delete pvc -l app=<service>. Stateless services recreate their scratch volume on start.
Disqualify the wrong target, check before acting, and stop on failure.
---
name: restart-stateless-service
---## Use This Skill When
Target is a Deployment. Disqualified if
it is a StatefulSet or owns a PVC.
Use restart-statefulset instead.
## Preconditions
Run: kubectl get deployment/<target>
If it is not found: STOP.
Run: kubectl get pvc -l app=<target>
If anything is returned: STOP.
Read-only checks run freely.
Any write asks first.
## Steps
1. kubectl rollout restart
deployment/<target>
2. kubectl rollout status
deployment/<target> --timeout=120s
3. Verify: pods Ready, error rate
flat for 2 min
## If a Failure HappensNever delete a PVC.
Never retry more than once.
Stop, report what you saw, and
hand back to a human.
Demo 3 · Mitigation
Same Model, Fixed Skill
sonnet-4-5 · fixed skill
restart-stateless-service / SKILL.mdafter the fix
description: Restart a stateless Deployment that is stuck, hung or unhealthy. Not for StatefulSets or anything that owns a PVC. Use restart-statefulset for those.
restart-statefulset / SKILL.mdthe one it loaded
## Preconditions
If any pod is Pending: do not restart. Run kubectl describe pod on it, read the Events, report the cause, and STOP. A restart cannot fix a pod that was never scheduled.
Same two steps in Claude Code (/plugin marketplace add) and Codex (codex plugin marketplace add).
~100 skills, 16 bundles
Skills are linked into bundles by name prefix (golang-* goes to the golang bundle), so authors edit one canonical file and every bundle that ships it picks up the change.
Illustrative example
Scoped Agents
An agent is a role: a few skills, rules for its answers, and things it refuses to do.
---name: data-analyst
description:Answer business questions from the
warehouse. Use for "active customers last
quarter", "churn by region".tools: [warehouse/query, catalog/search]
---## Skills to use
metric-definitions, sql-style, pii-rules
## Every answer shows
the SQL, the definition used, the date range
## Neverselect email, phone, or SSN columnsquery production databases## Escalate
metric not defined -> stop, ask <DATA-OWNER>
Skills carry our definitions
"Active customer" means what finance decided, not what the model guesses.
Every answer shows its work
The SQL, the definition and the date range, so a person can check the number.
"Never" is a reminder
A read-only login with masked PII columns is what stops the query.
The Linter Knows What a Vague Skill Looks Like
Hard errors
Frontmatter present and closed
name present
description 1,024 chars or less
At least one MUST, SHOULD or MAY
Warnings
name doesn't match the folder
No ## Anti-Patterns section
Sentences that start with "This" or "They"
Vague verbs: handle, manage, appropriately
Fuzzy amounts: some, several
A directive with no command or path
Review comment, not build failure
The CI check comments on the PR. It never fails the build. Anyone can contribute, one owner group approves (CODEOWNERS).
Context Is a Budget
Our token targets, per file.
Loads
Target
Hard ceiling
Always-on
1,500
3,000
Path-scoped
1,000
2,500
Triggered (a skill)
2,500
5,000
On-demand
1,500
4,000
Estimate: words × 1.3 to 1.8 = tokens.
Every rule lives in exactly one file.
Level 1 has a cap too: 2% of context in Codex.
Guardrails Outside the Skill
Skills say what to do. Hooks enforce what must never happen.
In a SKILL.md: suggested
"MUST NOT commit or push without explicit user instructions."
The agent reads it, and can still misapply it.
In a hook: enforced
Hard deny: reading secrets like .env and keys.
Hard ask: destructive git, reset --hard, push --force.
Runs every time. The model can't talk its way past it.
A skill explains the rule. An enforced hook can block the action even when the agent ignores it.
Shipping It Like Software
Versions, releases and docs, all from the files the agent already reads.
Release on change
A changed skill bumps its bundle's version, tags plugin/version, and posts to chat.
Pinned, then bumped
A weekly job opens a PR when a pinned external plugin has a newer release.
Docs from frontmatter
The catalog site is generated from the same frontmatter the agent reads.
What I Measured
What I Can and Can't Claim
No 10x claims. What I saw, what I didn't measure, and what it cost.
What I saw
The comments mistake stopped repeating once the rule was written down.
Demo 3: the old skill deleted the data 9 of 9 times on last year's models. The fixed skill stopped them.
What I didn't measure
Time to first PR on a repo you've never touched
On-call escalations per month
Days for a new engineer to merge a first PR
What it cost
Skill files grow. My Jira skill is past 1,000 lines.
A fix in my copy never reached the shared copy.
A skill can send the agent confidently wrong: 4 runs to 53 in the study.
07
---name:monday-morningdescription:Use when you're ready to write your first one.---
Monday Morning
Getting Started
The Starting Procedure
Checkout slip · your first skillDue: Monday
01Find the last time the agent got it wrong. A ticket, a PR comment, a chat you had to correct.
02Write the rule it broke. One line: what it did, what it should have done.
03Save it as a skill with a trigger. Say when it applies, so the agent finds it.
04Re-run the same task. Keep the skill if the failure is gone.
05Run it on a fresh task. Add a gotcha for each thing that still goes wrong.
06Share it. Put it where your team will find it.
How to Harvest a Skill
The longer version, once you have a few runs to learn from.
01Start with evidence
Do the task yourself, or use runbooks, schemas, reviews and incident reports.
02Run + label
Try it 3 to 5 times. Keep successful and failed traces; note why each failed.
03Inspect the trace
Read the whole run: wasted steps, false triggers, missing facts and corrections.
04Write the method
Distill reusable steps, preconditions, gotchas and what to do on failure.
05Script + validate
Code fragile repeats. Run skills-ref and a fresh task, then revise.
06Share upstream
Move it from your home folder into the shared library.
Yo dawg, I heard you like AI agents,
so I made an AI agent that writes skills
for your AI agents.
Our Own Rules
Steal This Structure
We wrote a constitution for how we write skills. Copy the shape and write your own specifics.
Spec first. No skill enters review without a written spec.
Dual-runtime parity. Every script ships on every platform your team uses, same commit.
Test-first gate. Unit, golden, and integration tiers, all passing before merge.
Human-in-the-loop. A write to an external system always waits for a yes.
One source of truth. Sync is one-directional by default; the reverse needs a human.
Layered credentials. Env var, then platform store, then config file. Never hardcoded.
Preserve what humans added. A sync may never silently erase a human annotation.
Simplicity. Standard library first. Every dependency has to earn its place.
References
Demystifying Agent Skills: Why They Work—Until They Don't Jiang, Huang, Xing et al., 2026arXiv:2608.14036
No. MCP gives the agent a tool or a data source. A skill says how your team uses it: the order, the checks, the gotchas.
See: Where Skills Sit (Part 1).
"How do you stop a skill doing something dangerous?"
Two layers. In the skill: a "use when", a precondition that says STOP, a failure section. Outside it: a hook that denies or asks, every time.
See: The Mitigation (Demo 3), Guardrails Outside the Skill (Part 6).
Q&A Backup · 2 of 4
Questions I Expect
"Does it still work after a model upgrade?"
Only if you check. Give each serious skill its own test suite, pin the model version in your evals, and rerun them on every upgrade. The big skills in the field notes already ship their own tests.
"Who owns a skill when its author leaves?"
Owned by a group. The name prefix says which team; CODEOWNERS says who approves changes. A skill with no owner group gets retired.
Q&A Backup · 3 of 4
Questions I Expect
"How many skills before it gets messy?"
By 100 skills the agent opens many wrong ones (the right share falls from 29.6% to 3.3%), but task success holds (36.4% to 39.3%). The tighter limit is the Level 1 budget: 2% of context in Codex.
"Can I use these across Claude, Copilot and Codex?"
Yes. Same SKILL.md, same open spec. Only the folder changes: .claude/skills, .github/skills, .agents/skills. Copilot and Codex also read Claude's .claude-plugin/marketplace.json.
Q&A Backup · 4 of 4
"Doesn't a 1,000-Line SKILL.md Defeat the Purpose?"
Yes. My copy of the Jira skill from Part 1 is 1,131 lines. Our own budget says a triggered skill should stay under 5,000 tokens.
It grew one gotcha at a time. Every addition was reasonable.
The fix is the folder: move reference material into references/ and fragile steps into scripts/.
The body keeps the procedure and the scars. Everything else loads only when needed.
One Open Standard, Many Clients
Compatible clients share the format. Install and discovery paths can differ.
Claude Code
GitHub Copilot (VS Code)
OpenAI Codex
Gemini CLI
JetBrains Junie
OpenHands
OpenCode
Mux
ZeroClaw
Autohand CLI
Open format, no vendor lock-in. Write the skill once; check each client's install path and feature support.
Compatible client list and specification: agentskills.io
You Don't Need a Perfect Taxonomy
With 100 skills on the shelf, the agent opens a lot of wrong ones. It finishes the job just as often.
Of the skills the agent opened, the share that were the "right" one: 29.6% → 3.3% as the pool goes from 5 to 100 skills.
It doesn't lose the right one. At 100, it still opened 54–74% of the right skills.
Task success over the same range: 36.4% → 39.3%.
Start building. Organize it later.
Jiang, Huang, Xing et al., arXiv:2608.14036 (2026), Section 5.5
SC1 group share by arm: Raw 59.1% · Workflow memory 55.7% · Skill 61.7–61.8%. SC2: Raw 37.3% · Workflow memory 33.3% · Skill 23.5%. SC3: Raw 3.6% · Workflow memory 11.0% · Skill 14.8%.
Appendix · Table 12
Lightweight Baselines, Full Detail
26 selected Terminal-Bench-2 tasks, 5 trials per task, 130 trials per condition.
Condition
Derived from
Success / total
Rate
Raw
None
65 / 130
50.0%
Short plan
Task instruction
62 / 130
47.7%
Test-first template
Workflow
77 / 130
59.2%
Workflow memory
Workflow
81 / 130
62.3%
Skill
Workflow
103 / 130
79.2%
Appendix · Table 13
Matched Token-Cost Comparison
83-task intersection with complete token metadata, equal task weighting.
Representation
Success
Input
Output
Total
Raw trajectories
64.1%
541.5K
14.2K
555.7K
Workflow memory
64.8%
417.9K
8.3K
426.2K
Skill
69.6%
511.7K
9.8K
521.5K
Skill vs Raw: +5.5pp success, −34.2K total tokens (better and cheaper). Workflow memory vs Raw: +0.7pp, −129.5K tokens (barely better, much cheaper). Skill vs Workflow memory: +4.8pp, +95.3K tokens (better but costlier).
Recall at k=100 remains 54.3–73.6% despite precision of 0.7–8.1%
Reading: exact ground-truth skill invocation is neither sufficient nor strictly necessary for task success. Agents often inspect multiple candidate skills without restricting use to the one annotated as correct.
Appendix · Table 16
Outcome Annotations Guide Construction
Agent / Benchmark
Mix
Labeled
Unlabeled
Gemini CLI / TB2
3 succ., 2 fail.
74.6%
40.0%
Gemini CLI / TB2
0 succ., 5 fail.
47.7%
43.1%
Codex / TB2
0 succ., 5 fail.
51.6%
38.7%
On Gemini with Terminal-Bench-2 and SkillsBench, labeled beats unlabeled at every ratio. Codex agrees once failed runs enter the pool, except at 4 successful / 1 failed on two benchmarks. Gemini on Terminal-Bench-Pro goes the other way at three ratios and ties at one. At 0-success mixes, both labeled and unlabeled skills sit below the raw baseline in all six setups (e.g. 50.0% Gemini TB2, 59.4% Codex TB2). Skills built purely from failed runs do worse than no skill at all.
Appendix · Figure 4
Cross-Framework Transfer
Skill and Workflow Memory built on Codex + GPT-5.3-Codex, evaluated on Gemini CLI + Gemini-3.1-Pro-Preview.
Target framework's own Raw baseline: 56%.
Transferred Skill: 62% to 84% across the six trajectory mixtures, +6 to +28 points over that baseline.
Transferred Workflow Memory: 54% to 70%, within 4 points of the baseline in five of the six mixtures.
Skill beats Workflow Memory in every mixture, by 2 to 30 points.
The comparison isolates framework transfer: prior experience is fixed at construction time, only the executing agent's prompting style, tool interface, and execution loop change.
Note: the paper evaluates transferred Skill and Workflow Memory against the target framework's Raw baseline; it does not separately transfer raw trajectories across frameworks, so "raw traces don't transfer" is this deck's inference from that framing, not a direct result reported in the paper.
Full References
Demystifying Agent Skills: Why They Work—Until They Don't. Jiang, Huang, Xing, Wu, Gao, Cao, Wang, Liu, Li. Princeton / UC San Diego / Stanford / USC / Johns Hopkins, 2026.arXiv:2608.14036
SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks. Li et al., 2026.arXiv:2602.12670
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces. Merrill et al., 2026.arXiv:2601.11868
8,135 trial records normalized from controlled experiments; 238 valid unique labels retained from 240 open-coded records, consolidated into 3 categories and 12 skill-use modes.
Benchmarks: Terminal-Bench 2.0 (89 tasks), Terminal-Bench-Pro (200-task public split), SkillsBench (86 tasks across 11 domains).
n = 5 trials per task, parallelism of 20, following the Harbor evaluation framework; Terminal-Bench-Pro entries use 130 trials per condition, missing/infrastructure-error trials counted as failures.
Four research questions: representation (Skill vs. Workflow Memory vs. Raw), outcome annotation, cross-framework transfer, and retrieval difficulty as the skill pool scales.
Agents: Codex + GPT-5.3-Codex and Gemini CLI + Gemini-3.1-Pro-Preview both ran the main experiments. Transfer moved Codex-built skills to Gemini CLI. Retrieval used Gemini CLI and Codex + GPT-5.4.
An LLM judge labeled the 528 paired runs. A human checked the taxonomy behind those labels (95.8% agreement).